At a Glance
| Code / tool | GALÆXI |
| Technical area | HPC, GPU acceleration, portability, high-order DGSEM, compressible flow |
| Challenge | Legacy Fortran CFD solvers face performance bottlenecks on CPUs and lack hardware portability across vendor GPUs, while maintaining high-order accuracy and stability near shocks. |
| CEEC contribution | Developed GALÆXI as an open-source, drop-in replacement for FLEXI; created a hybrid C++/Fortran (CUDA/HIP) architecture for hardware-agnostic portability while retaining and accelerating FLEXI’s localized FV subcell shock-capturing schemes on GPUs. |
| Key achievement | Demonstrated near-ideal scaling on up to 65,536 GPUs (67.1B degrees of freedom at 82.6% parallel efficiency on Frontier), achieved a 3.46x speedup over 32,768 CPU cores, and halved energy consumption. |
| Impact | Enables scale-resolving, high-fidelity simulations of complex compressible flows (e.g., transonic shock buffet) at previously inaccessible exascale regimes, while providing a reusable template for porting legacy Fortran codes. |
The Challenge
One of the lighthouse cases (LHC) in CEEC, LHC1, addresses the prediction of transonic shock buffet on aerodynamic wings under realistic flight conditions, characterized by high Reynolds numbers,  . Since experimental wind-tunnel testing has inherent scaling limitations, numerical simulations are an indispensable tool for capturing complex flow physics and designing fuel-efficient structures. However, accurately predicting buffet onset and frequencies requires scale-resolving simulations, and at these Reynolds numbers such simulations impose extreme computational demands due to strict spatial and temporal resolution requirements. At the same time, the process of shrinking transistors from chip generation to generation has become increasingly challenging and the resulting gains in computational performance have diminished in recent years. Consequently, legacy CPU-based simulation codes encounter severe throughput and scalability bottlenecks, rendering high-fidelity predictions computationally intractable within practical engineering workflows. To overcome these limitations and make high-Reynolds-number shock buffet predictions feasible, numerical solvers and high-performance computing (HPC) workflows must be explicitly refactored for modern hardware accelerators (e.g., GPGPU (general-purpose computing on graphics processing units) architectures). However, translating these workflows to such accelerators requires addressing fundamental architectural differences, often demanding extensive code refactoring and the selection of GPU-suited numerical algorithms.
The CEEC Solution
To tackle these challenges within CEEC, and to address the dual challenges of extreme scalability and hardware-agnostic portability without sacrificing high-order accuracy in the vicinity of discontinuities, GALÆXI [1,2] was developed as a GPU-accelerated evolution of the Fortran-based solver FLEXI [3]. GALÆXI is an open-source CFD solver designed for high-order simulations of compressible, turbulent flows on unstructured, curvilinear hexahedral meshes. To handle complex physics near shocks and maintain numerical robustness in underresolved regimes, it combines multiple flavors of the discontinuous Galerkin spectral element method (DGSEM) with localized finite-volume (FV) subcell shock-capturing schemes. Importantly, the user interface remains fully compatible with FLEXI, allowing GALÆXI to serve as a seamless drop-in replacement for running existing setups on GPU hardware without modification.
In the current age of heterogeneous computing environments, selecting a portable GPU porting strategy is a formidable task for legacy Fortran-based CFD codes. While various resources guide developers in making this impactful decision, no objective rules dictate the optimal choice for a given software package, forcing each project to evaluate approaches based on its unique requirements. This challenge is further compounded by the fact that committing to a strategy is rarely reversible once implemented.
To achieve hardware portability without sacrificing performance, CEEC implemented a hybrid C++/Fortran architecture that interfaces FLEXI’s Fortran codebase with vendor-native C++ programming models—specifically CUDA C++ for NVIDIA GPUs and HIP C++ for AMD GPUs. Leveraging DGSEM’s exceptional parallelization properties—which have previously demonstrated scalability to over 500,000 CPU cores—GALÆXI extends high-order efficiency to the GPU domain. This enables deployment across tens of thousands of accelerators for next-generation direct numerical simulations (DNS) and large eddy simulations (LES), while establishing a practical design template for porting legacy Fortran software to exascale HPC architectures.
Results
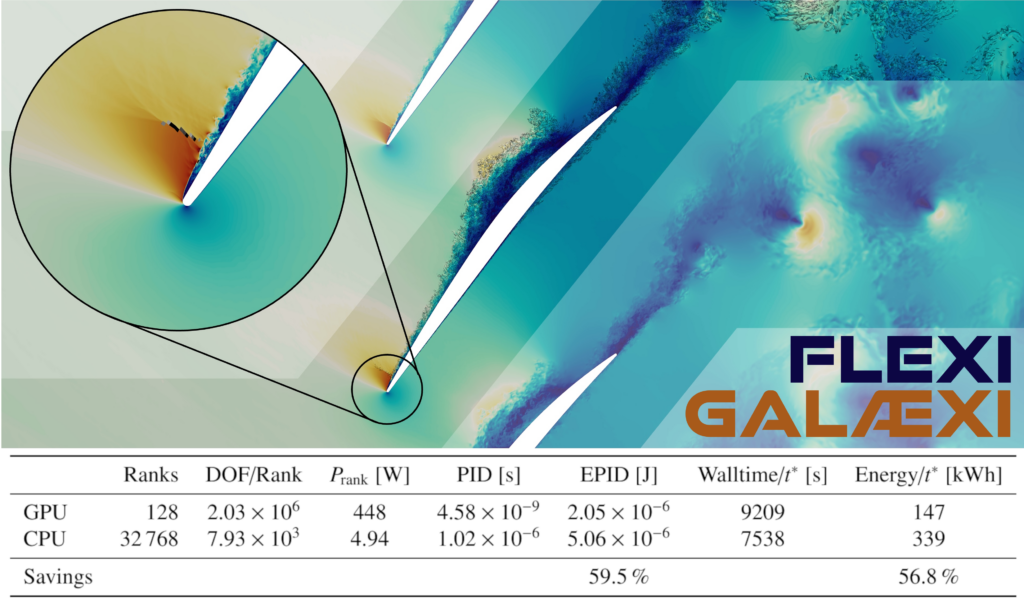
By successfully operationalizing the hybrid C++/Fortran porting strategy—interfacing FLEXI’s legacy codebase with native CUDA C++ and HIP C++ models without sacrificing computational performance compared to the original CPU-based FLEXI—the implementation unlocked major, quantifiable advancements in scalability, computational performance, energy efficiency, and physical simulation capability. Through its hybrid Fortran/C++ backend (CUDA for NVIDIA, HIP for AMD), GALÆXI achieved hardware-agnostic portability while demonstrating near-ideal strong and weak scaling up to 65,536 GPUs. In peak weak-scaling evaluations on the Frontier supercomputing system, GALÆXI simulated 67.1 billion degrees of freedom across 65,536 MI250X graphics compute devices (GCDs), single MI250X contains two GCDs, with a parallel efficiency of 82.6%. A production-scale wall-resolved LES of the transonic flow around the NACA 64A-110 airfoil on the LUMI supercomputer, running on 1,024 AMD MI250X GCDs, delivered a 3.46x improvement in time-to-solution compared to a legacy CPU run using 32,768 CPU cores. Despite the massive GPU acceleration, high-order accuracy and physical fidelity were rigorously preserved. Validated against the compressible Taylor-Green-Vortex and transonic airfoil configurations, results from the AMD HIP backend showed exceptional agreement with CPU reference data—exhibiting an average difference of only 0.41% in the surface pressure coefficient along the chord length of the NACA 64A-110. Beyond computational speedups, the GPU-accelerated implementation drastically cut power consumption. In a production-scale wall-resolved LES of the transonic flow around a NASA Rotor 37 rotor compressor blade, GALÆXI halved the energy required, reducing consumption from 339 kWh to 147 kWh per characteristic time unit compared to the CPU implementation, thereby cutting associated carbon emissions by 50%.
Impact on the Code
The implementation fundamentally transforms the operational capacity and efficiency of the simulation workflow, enabling massive-scale DNS and LES that were previously intractable on legacy CPU infrastructure. By scaling seamlessly up to 65,536 GPUs to handle simulations with 67.1 billion degrees of freedom, and by delivering a 3.46x speedup over tens of thousands of CPU cores, the framework achieves drastically reduced turnaround times for complex, high-Reynolds-number flow physics. Furthermore, the GPU acceleration drastically cuts power consumption—halving energy requirements per characteristic time unit relative to the CPU implementation, thereby significantly reducing both operational costs and associated carbon emissions.
From an operational and architectural perspective, the toolchain maximizes usability and hardware-agnostic flexibility. Since GALÆXI preserves full interface compatibility with the FLEXI framework, it acts as a seamless drop-in replacement that requires zero modifications to existing user setups across heterogeneous architectures (supporting both NVIDIA CUDA and AMD HIP). Beyond its immediate application domain, the hybrid C++/Fortran integration strategy establishes a practical, extensible design template that can be directly reused to port other legacy Fortran-based computational software to modern exascale high-performance computing environments.
Contribution to the State of the Art
Technically and scientifically, GALÆXI advances the state of the art by successfully unifying hardware-agnostic portability, massive GPU scalability, and robust, low-dissipative shock capturing within a single high-order framework. Previous high-order GPU-ready CFD codes for compressible flows typically relied on overly dissipative artificial viscosity or entropy-filtered methods or were restricted to vendor-locked CPU/GPU architectures. GALÆXI represents a path to eliminating these constraints by integrating localized finite-volume subcell shock capturing with a hybrid Fortran/C++ backend that scales efficiently across NVIDIA and AMD exascale systems. Because the vast majority of legacy scientific codes are built on Fortran or C++, this hybrid porting architecture serves as a directly reusable blueprint for the broader computational physics community. Consequently, it removes previous computational and numerical barriers, rendering scale-resolving simulations of complex, compressible, high-Reynolds-number flows computationally practical at scales previously considered inaccessible.
CEEC advanced the high-order HPC-friendly solver FLEXI by integrating localized finite-volume subcell shock capturing into a hardware-agnostic, GPU-accelerated DGSEM framework (GALÆXI), enabling scale-resolving, low-dissipative simulations of complex compressible flows at previously inaccessible exascale regimes.